

Optimize Dashboard Performance with Persisted Aggregations
Available: Optimize Dashboard Performance with Persisted Aggregations v1.252.0
Optimize Dashboard Performance with Persisted Aggregations is available from version 1.252.0.
Dashboards that use queries based on persisted aggregations refresh faster and respond more quickly because they query pre-computed results instead of reprocessing raw log data. The dashboard appearance and behavior remain unchanged.
When you create dashboards with widgets that run computationally intensive aggregation queries, you can improve performance by using Persisted Aggregations. A persisted aggregation runs an aggregation query on a schedule and stores pre-computed results in a dedicated repository. When dashboard widgets query this data, LogScale retrieves the stored results instead of recomputing the aggregation from raw logs.
Performance Benefits
Using persisted aggregations in dashboards provides these performance advantages:
Faster dashboard refresh times because queries access pre-computed results
Lower resource costs for compute-intensive aggregations
The dashboard layout, widget types, and user interactions remain exactly the same whether using persisted aggregations or querying raw data directly.
Example: Using Persisted Aggregations in Dashboards
Dashboard widgets display pre-computed results using the
readPersistedAggregation() function, which
retrieves stored aggregation results instead of reprocessing raw log
data. Figure 174, “Dashboard Using Persisted Aggregation Results”
shows a dashboard table widget displaying API metrics retrieved from a
persisted aggregation:
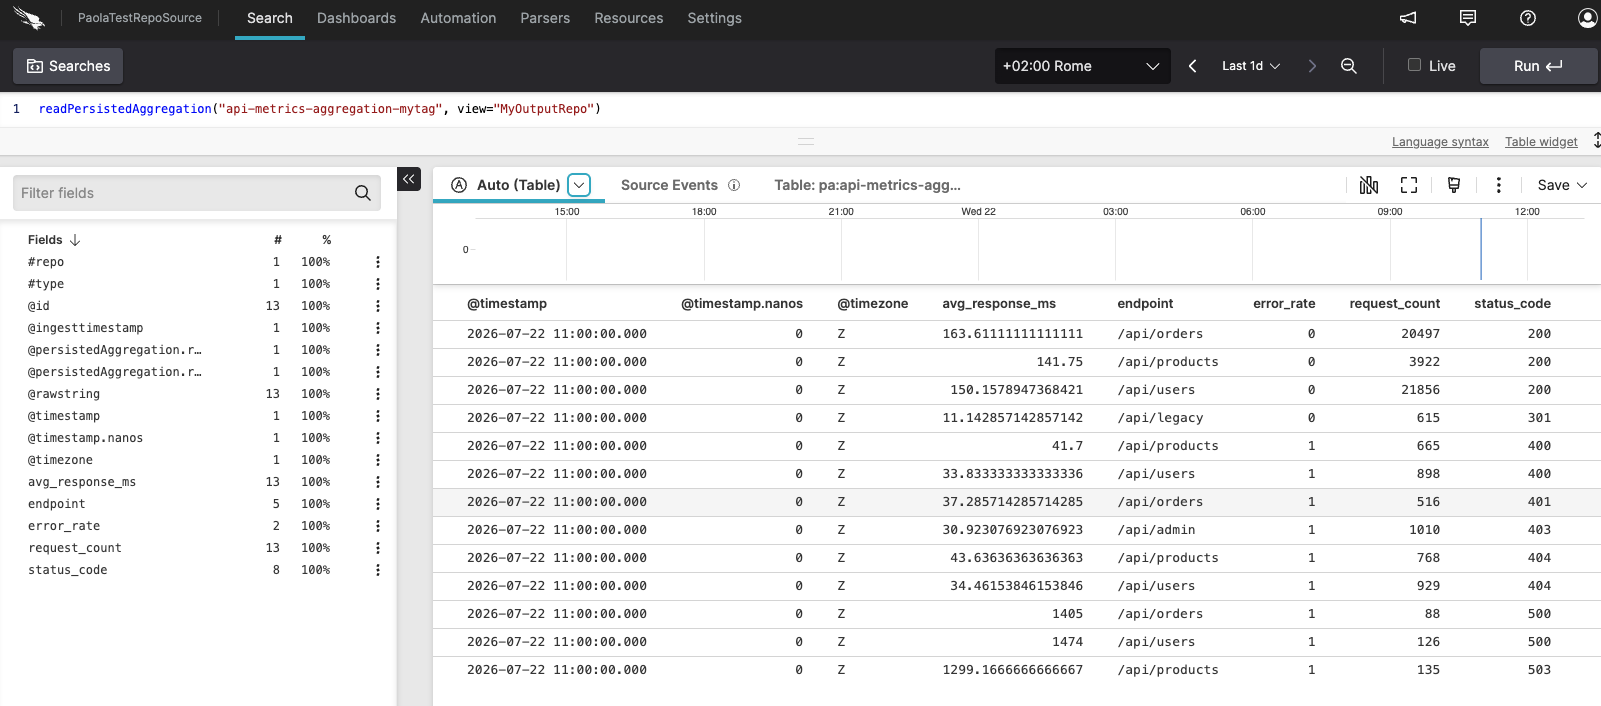 |
Figure 174. Dashboard Using Persisted Aggregation Results
The widget uses the following query to retrieve the pre-computed results:
readPersistedAggregation("api-metrics-aggregation-tag", view="MyOutputRepo")
The view parameter specifies
the repository containing the persisted aggregation output. For
additional examples of this function, see
readPersistedAggregation() Examples.
For a step-by-step demonstration of the performance difference, see Worked example: before and after persisted aggregation.
When to use persisted aggregations
Consider using persisted aggregations for dashboards that:
Are accessed frequently by multiple users
Run complex aggregations over large datasets
Display metrics that do not require real-time precision
Need consistent response times regardless of data volume
For information about creating and managing persisted aggregations, see Persisted Aggregations. For query syntax requirements, see Query Language Requirements.
Worked example: before and after persisted aggregation
The following example shows how to convert a slow dashboard widget to use a persisted aggregation. In this example, a time chart displaying hourly log volume by source over seven days takes tens of seconds to execute. After you create a persisted aggregation and update the widget query, the same chart returns in less than one second with identical output.
Start by running the aggregation query you want to display in your dashboard widget. For example:
logscaletimechart(span=1h, function=count(), by=source)The following screenshot shows a production example using a more complex query; the concept and performance characteristics of a query before PA are the same:
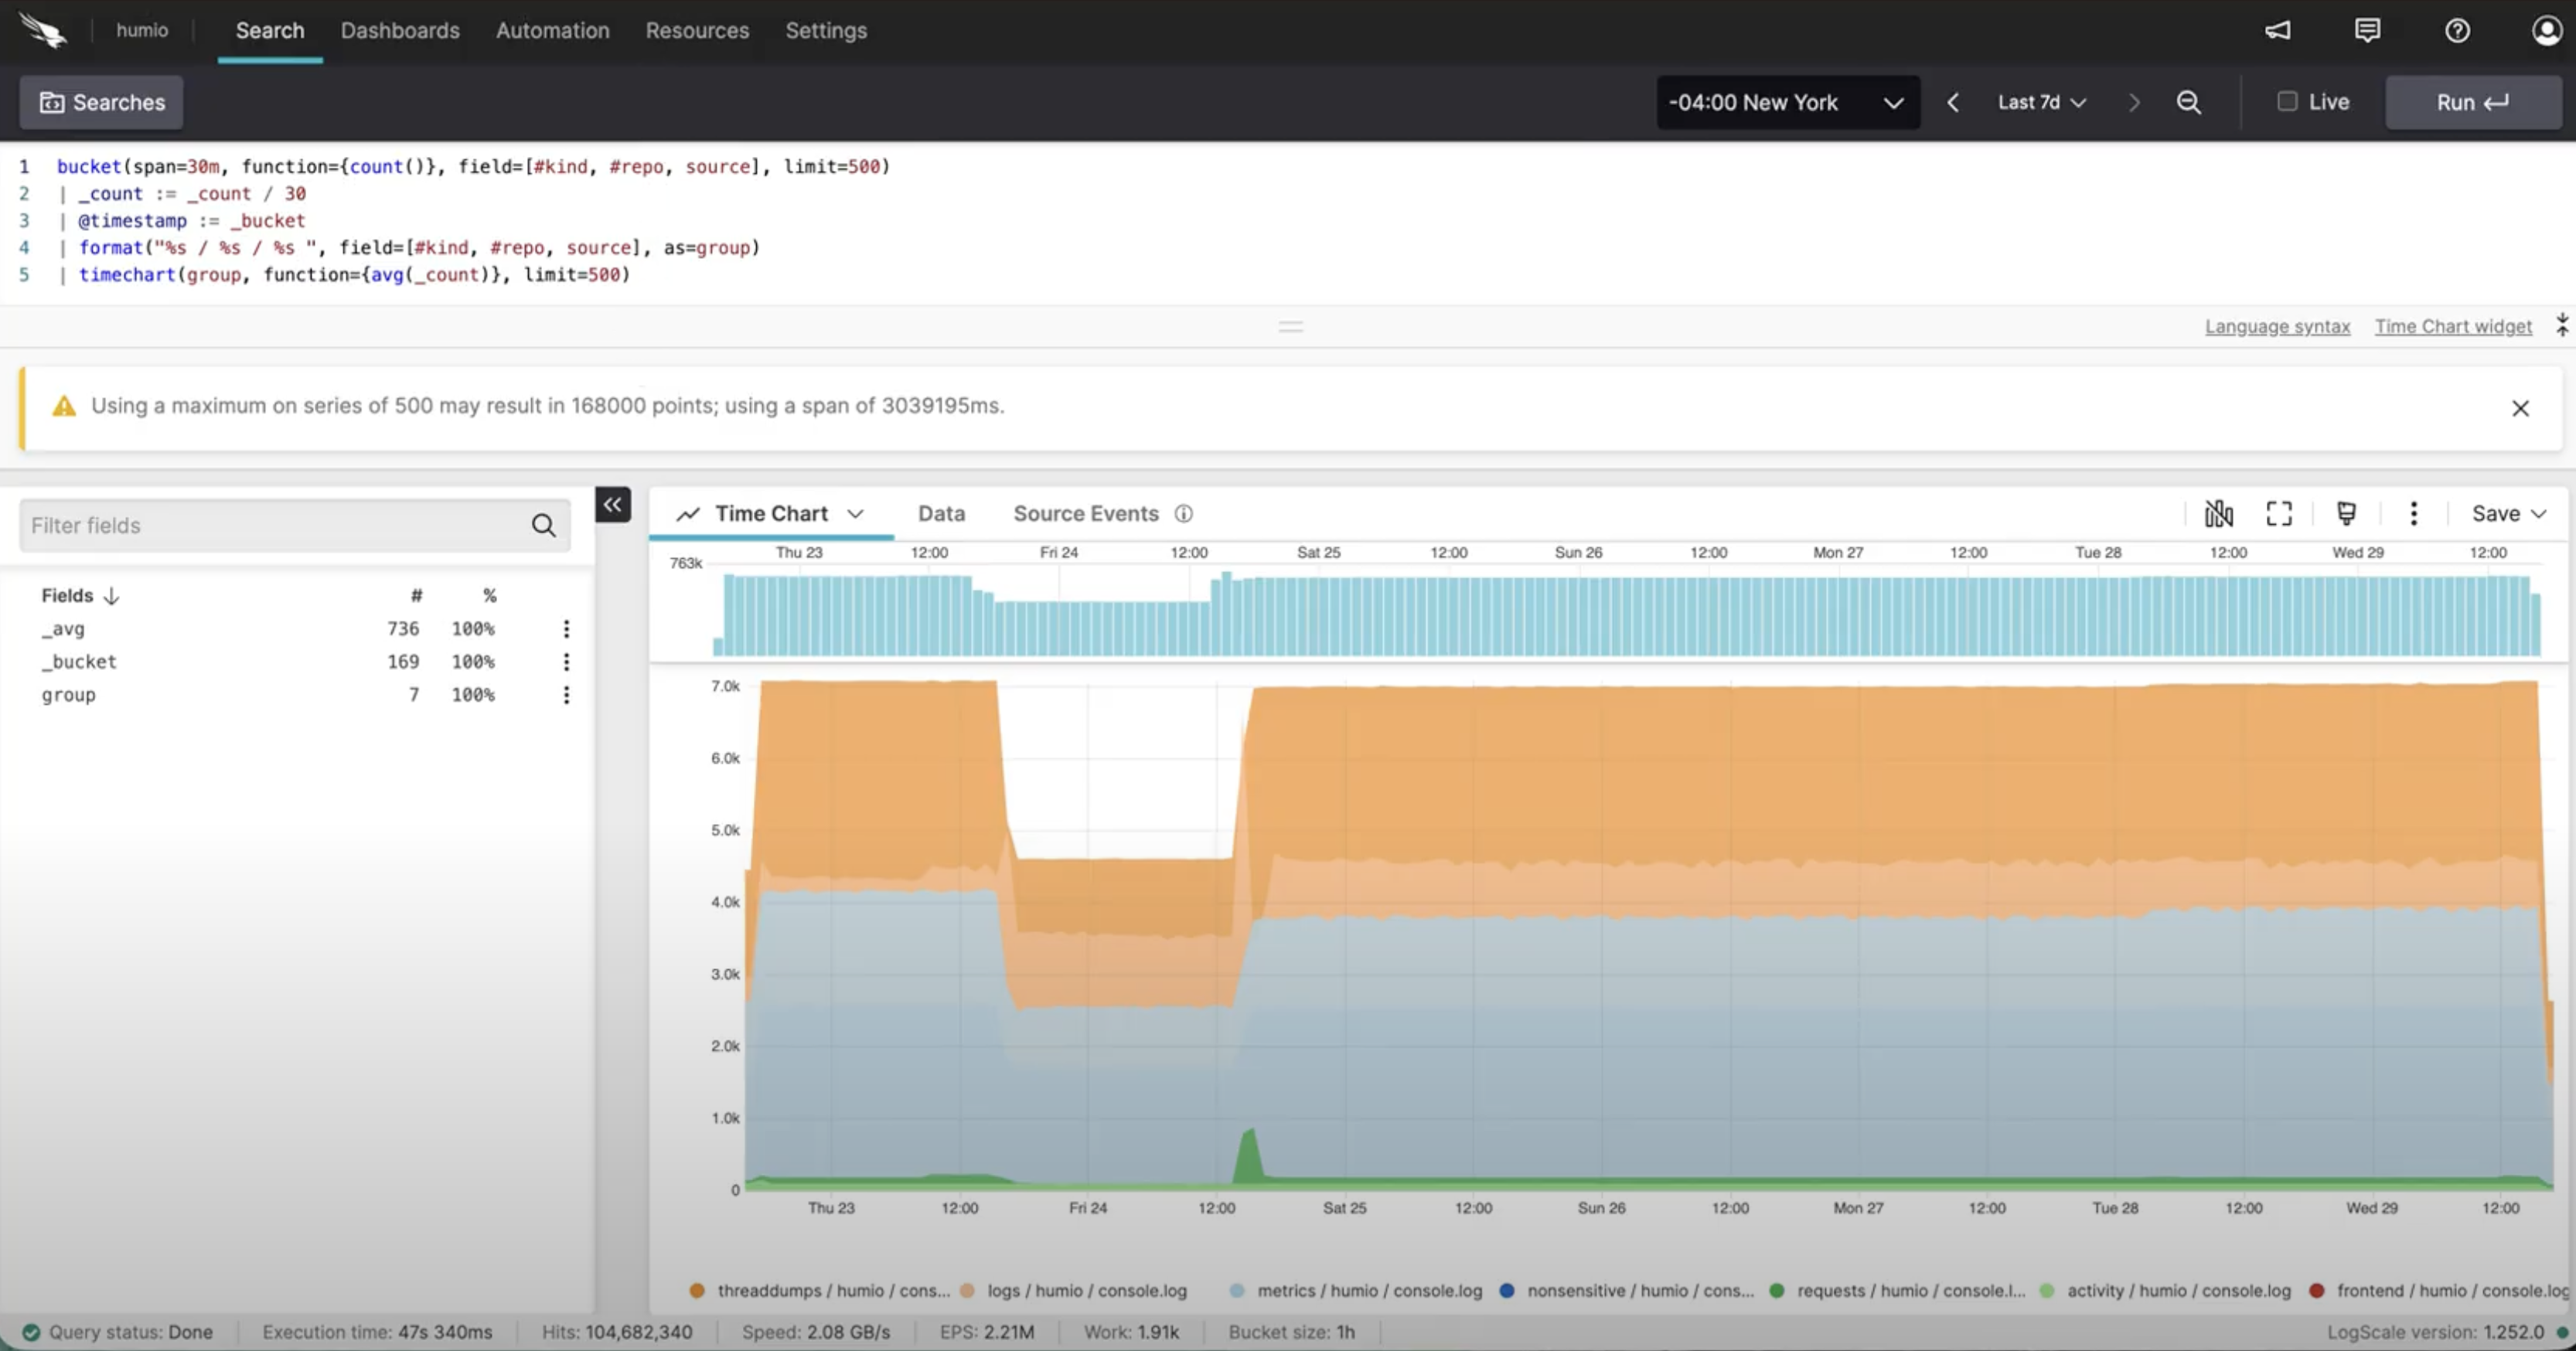
Figure 175. Raw Query Before Persisted Aggregation
Note the execution time in the status bar. Over such a large dataset and a long time range, the query must scan raw log events and takes more than 47 seconds.
Create a persisted aggregation in the same source repository using the same aggregation query. As part of the configuration, create a dedicated output repository to store the pre-computed results and assign a descriptive tag, for example
log-volume-by-source. The tag identifies the pre-computed results when you'll read them with the PA query. For full configuration instructions, see Configure Persisted Aggregation Properties.Wait for the historical backfill to complete before updating the dashboard widget. You can monitor the progress in the Persisted aggregations overview. The health status indicator in the table changes from Backfilling to Running when the backfill is complete.
Use a query that reads from the persisted aggregation by updating the existing widget with or by creating a new one. In either case, use the following query:
logscalereadPersistedAggregation("log-volume-by-source") | timechart(span=1h, function=sum(_count), by=source)The
readPersistedAggregation()function retrieves the pre-computed hourly counts. Thetimechart()function usessum()to correctly aggregate those counts across the selected time range. The widget displays identical results to the original query.
Figure 176, “Persisted Aggregation Query Execution Time” shows the updated query returning the same results in less than one second:
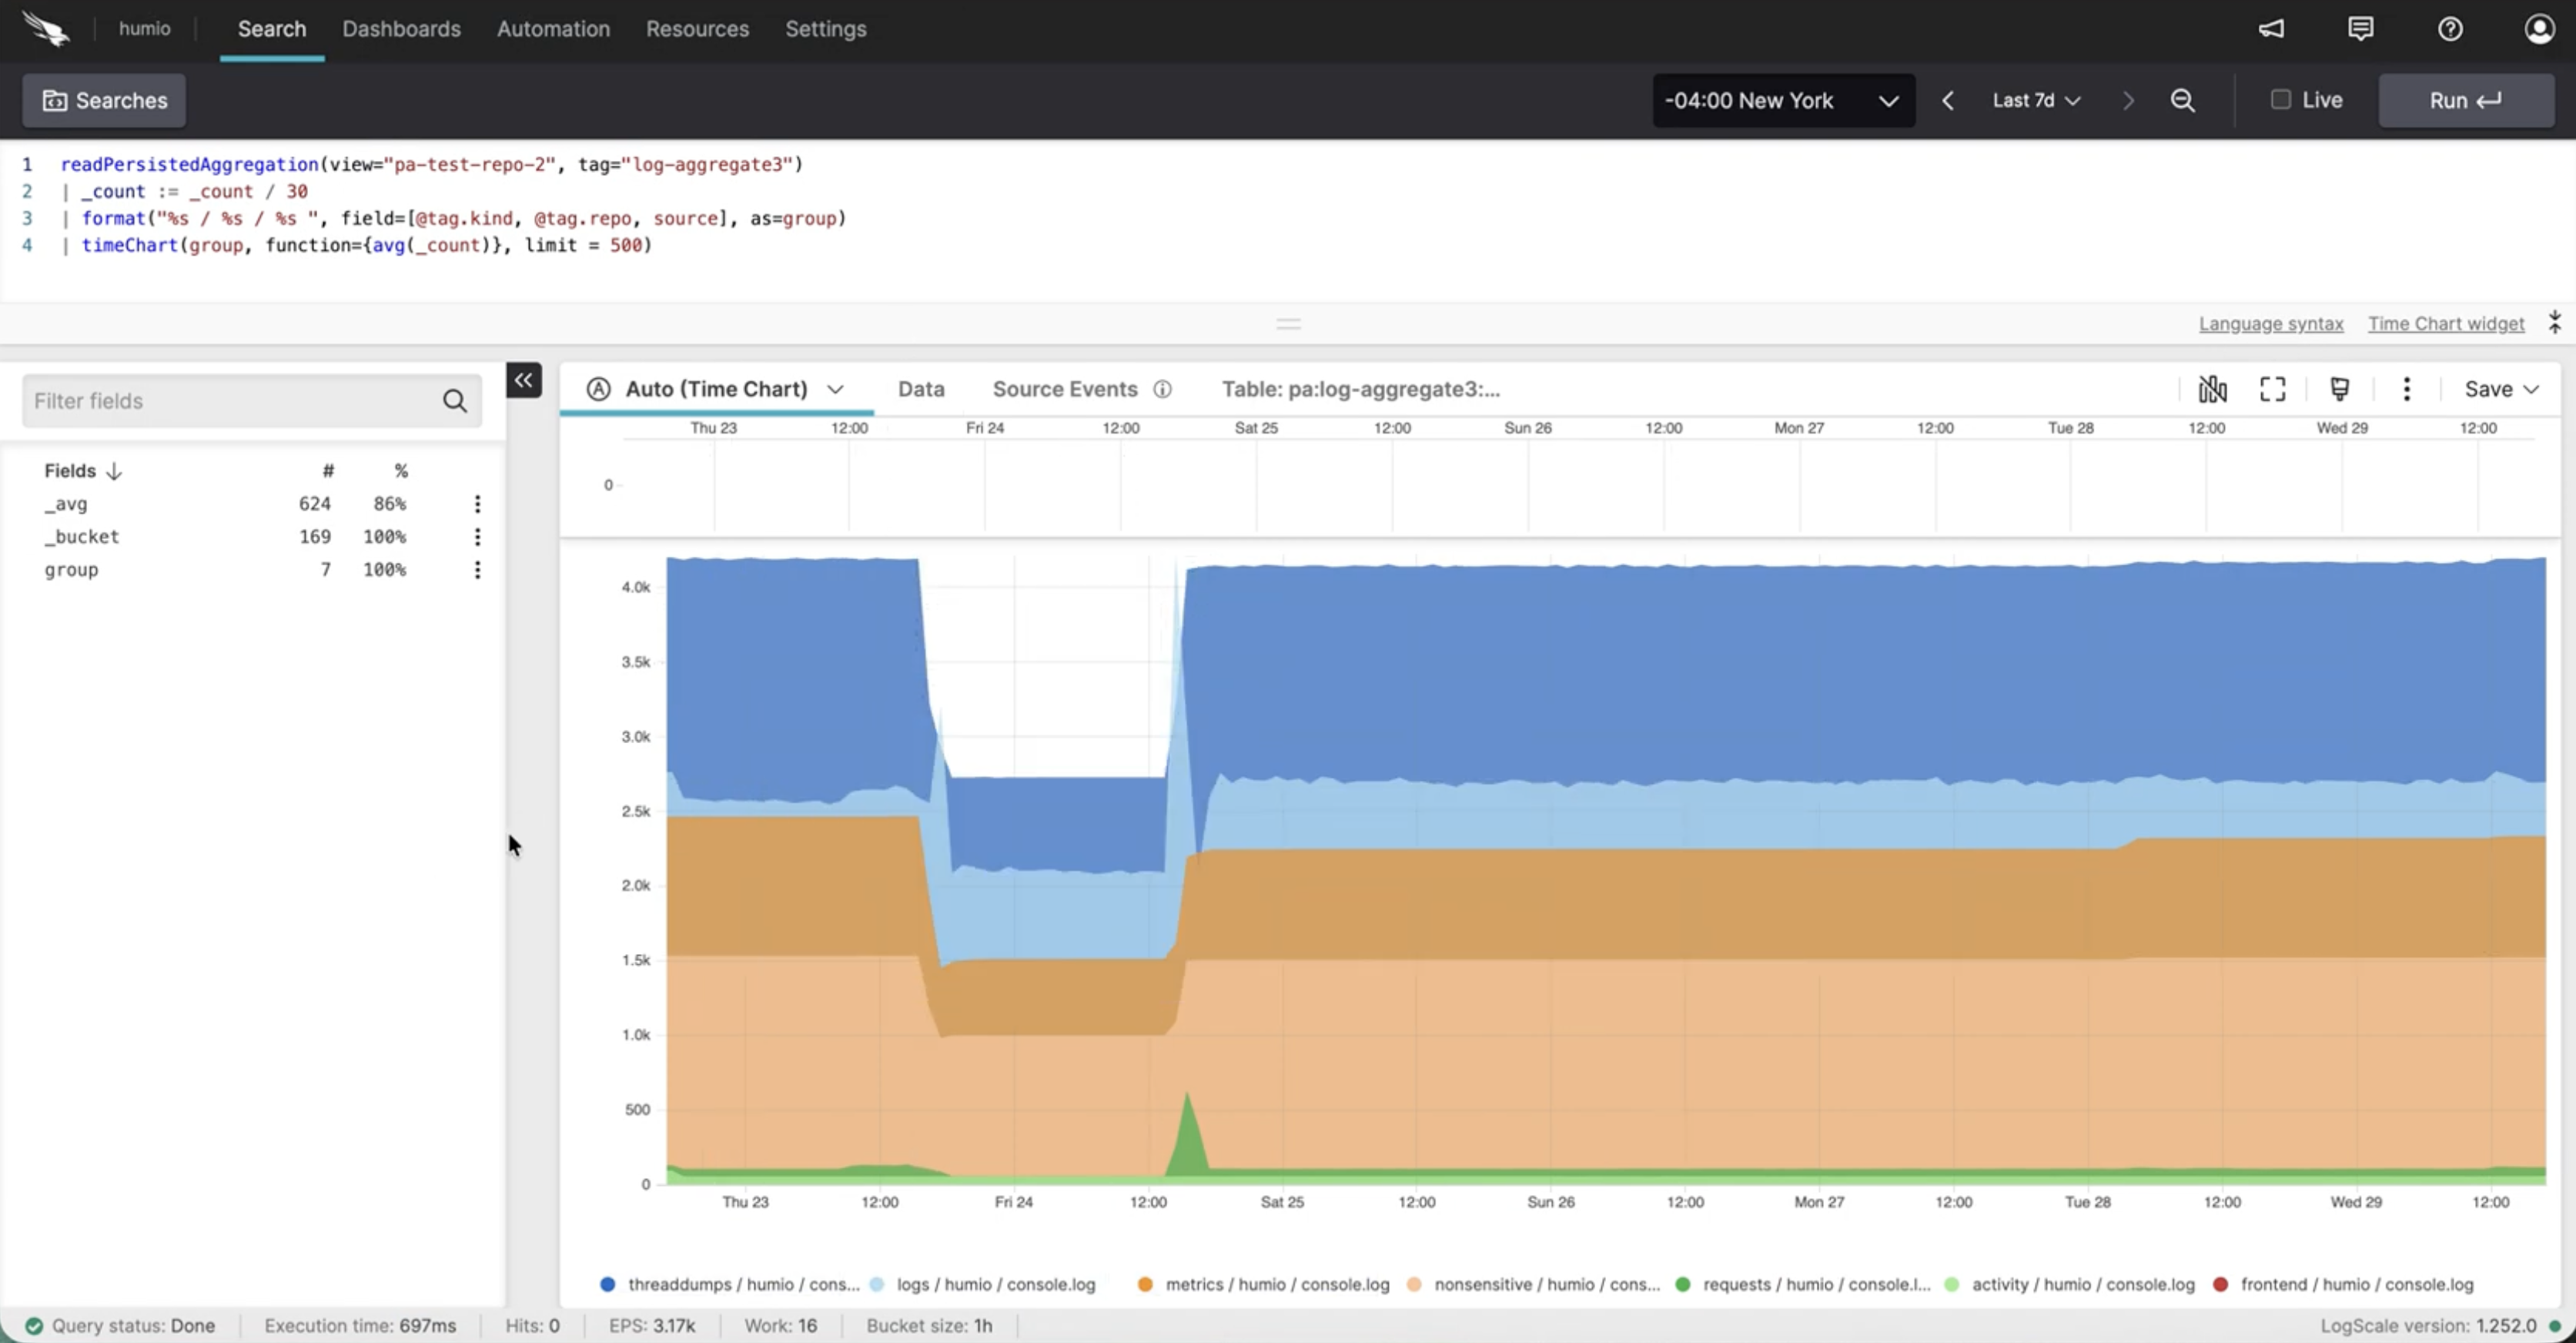 |
Figure 176. Persisted Aggregation Query Execution Time